Platform Migration
15 Microservices to Amazon EKS
Completed a six-week, zero-downtime migration with infrastructure defined in Terraform, application packaging in Helm, and deployment through an ArgoCD GitOps pipeline.
AWS EKS·Terraform·Helm·ArgoCD
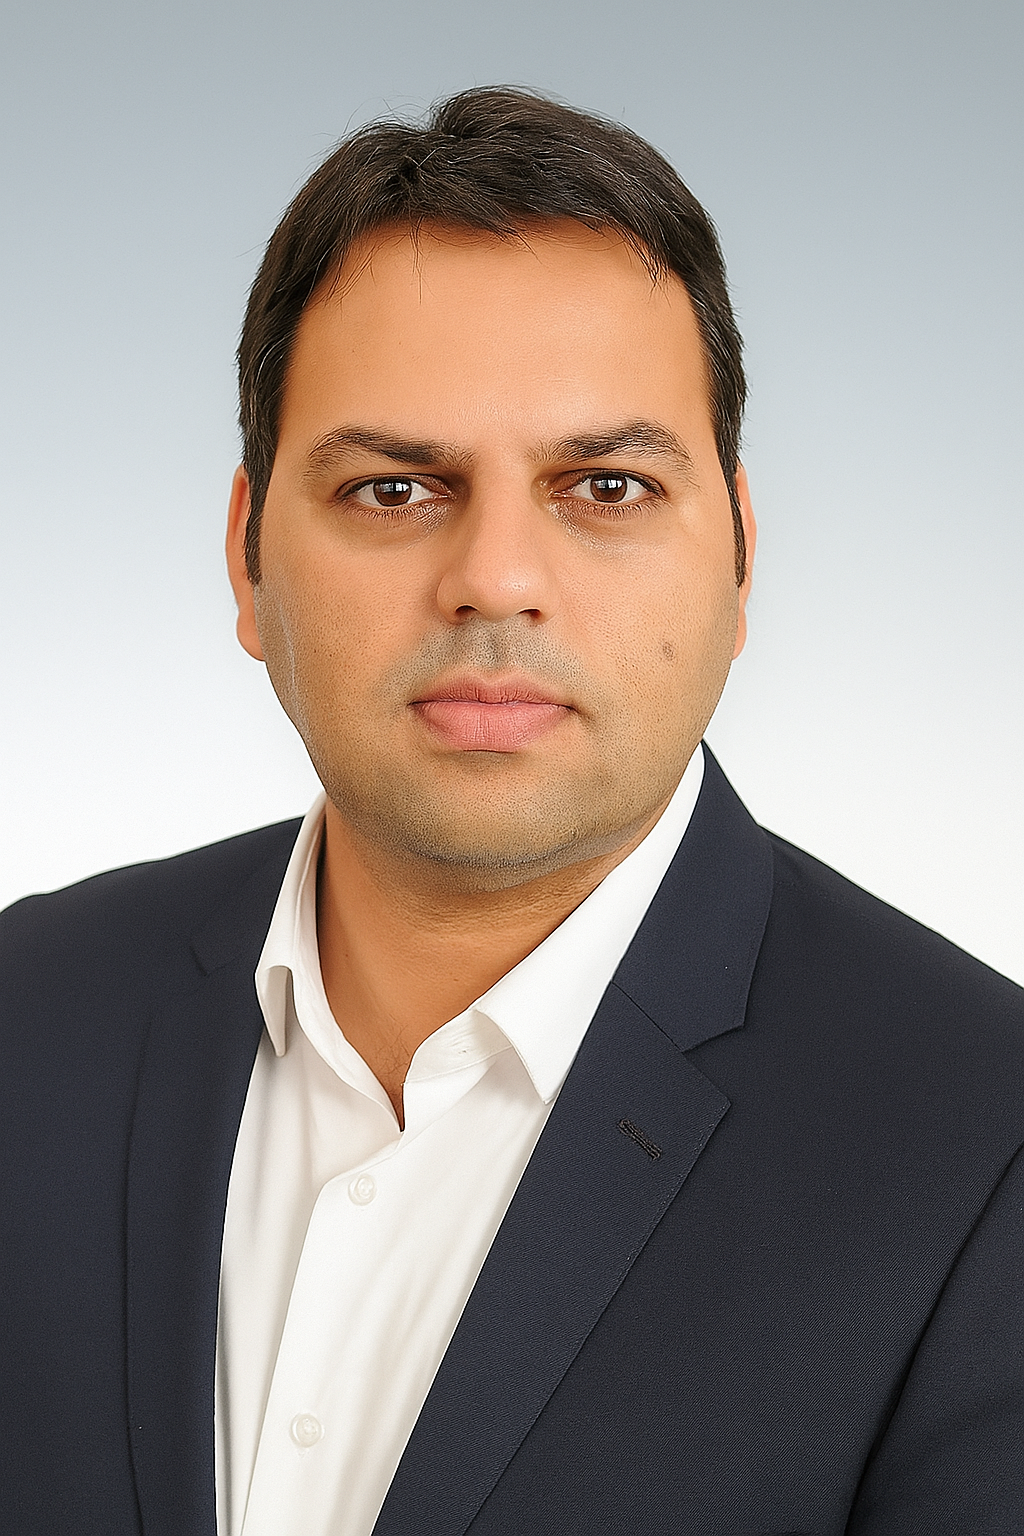
Vikram Singh
I build reliable cloud platforms and production AI infrastructure—combining 15+ years of infrastructure experience with hands-on Kubernetes, Terraform, CI/CD, MLOps, and LLM serving expertise.
Senior / Lead DevOps · Platform Engineering · SRE · MLOps · Based in India
Reliability · Automation · Security · Cost
Selected Impact
A selection of production results across AI infrastructure, cloud migration, and deployment automation.
Reduced monthly inference spend from $13K to $9K through attribution, autoscaling, spot capacity, and vLLM tuning.
Moved to Amazon EKS in six weeks with zero downtime using Terraform, Helm, and ArgoCD.
Right-sized inference clusters and combined spot fleet with reserved GPU capacity, saving $8K per month.
Reduced deployment time from two hours and enabled 50+ daily model deployments through GitOps automation.
About Me
I have spent 15+ years building and scaling infrastructure for enterprises and startups. My recent work focuses on moving LLM systems out of notebooks and into reliable production environments with strong serving infrastructure, cost visibility, and operational ownership.
I work across the full platform lifecycle: architecture, Infrastructure as Code, Kubernetes, deployment automation, observability, security, and optimization. I care as much about measurable business outcomes as I do about clean implementation.
Discuss a full-time opportunity →Measure before optimizing
Establish attribution, baseline performance, and observable outcomes before changing production systems.
Automate repeatable operations
Use IaC, CI/CD, and GitOps to make infrastructure and deployments consistent, reviewable, and repeatable.
Design for day-two ownership
Build monitoring, security, documentation, and cost awareness into the platform rather than adding them later.
Selected Work
Coordinating architecture within a three-engineer team, I helped reduce monthly GPU spend by 30% in 60 days without degrading model quality or response latency.
Read the full technical case study →30%
Spend reduction
60
Days to rollout
118
Idle hours removed / week
0
Latency regression
Platform Migration
Completed a six-week, zero-downtime migration with infrastructure defined in Terraform, application packaging in Helm, and deployment through an ArgoCD GitOps pipeline.
Deployment Automation
Reduced model deployment time with an ArgoCD GitOps pipeline and automated testing, enabling more than 50 model deployments per day with no manual deployment steps.
Technical Expertise
A production-focused toolkit spanning infrastructure, delivery, reliability, and AI platforms.
Kubernetes cluster administration and operations
Kubernetes platform and workload security
Contact
I’m interested in full-time Senior or Lead opportunities across DevOps, Platform Engineering, SRE, and MLOps. If my background aligns with your team, I’d be glad to discuss the role.
Best fit: Teams building cloud-native platforms, production AI/ML infrastructure, or large-scale deployment and reliability systems.